顯示具有 Gemini 標籤的文章。 顯示所有文章

2026年4月24日 星期五

How to leverage Google TPUs and the JAX framework for fine-tuning and post-training Large Language Models (LLMs)

2026 AI Benchmarks: The Power of TPU and JAX

In the current competitive landscape of AI models, Google’s Gemini-3.1-Pro leads the leaderboard with an Arena Elo of 1505. This performance is rooted in the synergy between specialized hardware and high-performance software frameworks.

The Advantages of TPUs

Gemini 3 Pro was trained using Google’s Tensor Processing Units (TPUs). Key benefits include: 

  • Massive Computation: TPUs are specifically designed to handle the heavy computational demands of training LLMs, significantly outperforming CPUs in speed.
  • High-Bandwidth Memory: This allows for handling larger models and batch sizes, which directly contributes to higher model quality.
  • Scalability: TPU Pods (large clusters) provide a scalable solution for the increasing complexity of foundation models.
  • Sustainability: The efficiency of TPUs aligns with Google's commitment to sustainable operations.

JAX and ML Pathways
The software foundation for these models includes JAX and ML Pathways. JAX is the core machine learning framework driving Gemini, Gemma, and Vue. It offers advanced features like just-in-time (JIT) compilation and automatic differentiation

Tunix (Tune-in-JAX): A Specialist for Post-Training

As AI development shifts from pure scale to deeper "Intelligence," a lightweight JAX-based library built specifically for post-training.

Two Key Phases of LLM Training
LLM development is categorized into two distinct stages:

Pre-training:
  • Core Goal: Next Token Prediction.
  • Data Source: Massive amounts of unstructured raw text.
  • Result: Basic language capabilities that may not always align with human expectations.

Post-training (Tunix Core Domain):
  • Core Goal: Building strong reasoning abilities and aligning with human preferences.
  • Key Technologies: Supervised Fine-Tuning (SFT) and Reinforcement Learning (RL).
  • Result: Safe, controllable instruction models with deep logic.
The Path to Advanced Intelligence
Post-training is essential for reaching higher stages of AI development:
  • Post-training Scaling: Focuses on role-setting, logic restructuring, and mimicry.
  • Test-time Scaling: Enables "long thinking" and self-verification/reflection.
  • Agentic Scaling: Facilitates "AI talking to AI" through collaboration and co-learning.

Tunix Architecture and Ecosystem

Tunix provides a comprehensive matrix of post-training capabilities for models like Gemma, Llama, and Qwen.
  • Hardware Layer: Supports Google Cloud TPUs, multi-host GPU clusters, and CPU hosts.
  • Foundation Frameworks: Integrates JAX, Flax NNX, Optax, and vLLM/SGLang for efficient rollout and inference.
  • Algorithm & Workflow Layer: Includes SFT (full weight or PEFT), RL (PPO, GRPO, DPO), and Knowledge Distillation.

Deep Dive: Knowledge Distillation

To enable smaller "Student" models to capture the intelligence of large "Teacher" models, Tunix utilizes Knowledge Distillation.

Mechanism and "Dark Knowledge"Knowledge distillation involves a Teacher Model (large and experienced) passing its behavior to a Student Model (small and learning). A core component is Temperature Scaling (T > 1):


Higher temperatures produce "Soft Targets". These contain Dark Knowledge, which reveals how the Teacher model relates different categories.

Optimization through Loss Functions

The Student model is optimized using a combined loss function:


L_{KD} (Distillation Loss): Measures the difference between the student and teacher outputs using KL-Divergence.
L_{CE} (Student Loss): Measures the difference between the student's prediction and the "True Labels" (Ground-Truth).

Conclusion

By combining Tunix with the power of TPU and JAX, developers can achieve state-of-the-art training performance. This ecosystem allows organizations to remain GCP solutions while delivering safe, high-quality, and logically sound AI models.

#TPUSprint

==============================================================

2026 AI 巔峰之戰:為何選擇 TPU 與 JAX?

在當前 AI 模型評測中,Google 的 Gemini-3.1-Pro 以 1505 的 Arena Elo 高分領先群雄 。這類頂尖模型的成功,很大程度歸功於其底層硬體與軟體框架的結合。


TPU:專為大模型誕生的硬體
Gemini 系列模型皆採用 Google 的 Tensor Processing Units (TPUs) 進行訓練 。相比於傳統 CPU,TPU 具備以下優勢:
  • 強大的運算能力:專為處理 LLM 訓練中的海量計算而設計 。
  • 高頻寬記憶體 (HBM):可容納超大模型與 Batch Size,提升模型品質 。
  • 高度可擴展性:透過 TPU Pods(大型集群)實現分散式訓練,滿足基礎模型日益增長的複雜度 。
JAX 與 ML Pathways:軟體核心
在軟體層面,這些模型採用 JAX 與 ML Pathways 進行開發 。JAX 是一個具備即時編譯(JIT)與自動微分功能的強大框架,同時也是驅動 Gemini、Gemma 與 Vue 的核心引擎 。

Tunix (Tune-in-JAX):專為「後訓練」打造的利器隨著 AI 發展,業界已從單純追求模型規模轉向對「智能」的深度挖掘。

LLM 訓練的兩個關鍵階段
根據簡報,LLM 的成長可分為兩個階段 :

預訓練 (Pre-training):

  • 目標:預測下一個 Token 。
  • 來源:海量未結構化原始文本 。
  • 結果:獲得基礎語言能力,但不一定符合人類預期 。

後訓練 (Post-training) —— Tunix 專屬領域 :

  • 目標:建立強大推理能力並與人類偏好對齊 。
  • 技術:監督式微調 (SFT) 與強化學習 (RL) 。
  • 結果:產出安全、可控且具備深度邏輯的指令模型 。

智能演進的路徑
在 AI 發展的不同階段,微調與後訓練扮演著關鍵角色 :
  1. Post-training scaling:處理角色設定、邏輯重組與模仿 。
  2. Test-time scaling:實現「長時間思考」與自我驗證 。
  3. Agentic Scaling:達成 AI 之間的協作與共學 。

Tunix 的底層架構與技術矩陣
Tunix 提供了一站式的後訓練能力矩陣,支持包括 Gemma、Llama 與 Qwen 在內的主流開源模型

核心技術矩陣 

  • SFT (監督式微調)
  • PEFT (參數高效微調)
  • Preference Tuning (偏好微調)
  • RL (強化學習)
  • Model Distillation (模型蒸餾)
架構層次 Tunix 的架構層次分明,確保了極致效能與開發彈性:

硬體層:支援 Google Cloud TPUs、GPU 集群與 CPU 
框架層:整合 JAX、Flax NNX、Optax、vLLM/SGLang 等前沿工具 
組件層:負責分散式狀態管理(Sharding, Mesh)與訓練迴圈調度 

深度解析:知識蒸餾 (Knowledge Distillation)

為了讓較小的模型(Student Model)也能具備大型模型(Teacher Model)的智慧,Tunix 引入了 知識蒸餾 技術 。

運作原理

知識蒸餾透過讓學生模型模仿老師模型的「行為」與「輸出」,實現知識的轉移 。其核心公式涉及 溫度縮放 (Temperature Scaling) :

當 T > 1 時,模型會產生「軟目標」(Soft Targets),這些目標包含了所謂的 Dark Knowledge,能幫助學生模型理解類別之間的細微關聯(例如:這張圖看起來 90% 像狗,但也包含 5% 狼的特徵)


損失函數 (Loss Functions)

學生模型的優化目標是最小化總合損失 :

L_{KD} (蒸餾損失):利用 KL-Divergence 計算學生與老師輸出差異 。

L_{CE} (學生損失):計算學生預測與真實標籤 (True Labels) 的差異 。


總結

透過 Tunix 與 TPU/JAX 的結合,可以利用強大GCP TPU的後訓練技術,快速打造出高效、安全且具備高度推理能力的專屬 LLM,在 AI 的下一個發展階段佔得先機 。


2024年8月11日 星期日

Google I/O Connect 2024 速記


大家好我是Jerry老師,週一要上班了,趕快來把上週在Google I/O Connect 2024 的經驗做個分享,疫情後連續兩年參加Google I/O 的活動,之前在上海,今年在北京。晚上的晚宴很有趣,這次有東南亞的社群朋友,很熱鬧,中、英交叉主持。


大中華的主管們分享


有趣的問題,大家猜到了嗎


全球生態圈的大老闆分享


今年辦在北京國家會議中心(China National Convention Center)

今年換穿白色制服的Google開發者,可以直接入場


入口報到


從另一個角度拍攝,大家魚貫上手扶梯

一樣看起來很酷炫的Keynote開場,滿滿的人

一如往常Google介紹貢獻,有個編譯夢想的計畫,很特別

透過AI創造很多應用的計畫

各項培育計畫


GenAI的個人化應用種類


完整的生態圈


Chrome也有 AI計畫
基本上 Google生態圈的產品,都已經開始支援Gemini做各種不同的應用
相當期待

Google的公益也做了不少

聽障的公益

現場手語辨識


可以提足球,透過AI評分


Google也是要跟NVIDIA一起串一下,這邊提的是Gemma支援NIMs

Google重視的負責任AI

這邊的RGAI很完整


VertexAI開發的環境

以前的TensorFlow JS現在改為為Web AI 

現在也支持LLM


去年就有介紹的Visual Blocks 今年功能更強大了。


支援幾個常見的LLM模型


這個真的滿重要的,因為現在LLM可以讀超過我們人類讀的速度


在Web上做推論


中間還有特色禮品跟飲品


這個概念很不錯,看起來就是透過Google技術把最後一哩路走完


PaliGemma是一個可以做圖文的雙模態

這的確是Google的夢想,也是Jerry老師的夢想,只有這樣這個世界才會透過科技更強大

Google Cloud分享最新動態

事實上也是繞著GenAI主題在討論


透過生成式AI評分,相當有趣的應用,因為Gemini已經可以多模態,

所以他透過影片來進行分析。

透過這張圖來解釋 嵌入的關係


在Firebase上的應用


在Android上的應用


11:00的時候代表台灣進入閉門會議,很特別的經驗。


這個要講出RAG的梗,因為資料不夠,導致幻覺


示範了透過對話的方式針對Ray這份文件做互動


Ray與K8S的整合應用


KubeRay的概念很棒


這個是三星的案例,透過Ray來進行機器學習服務


接下來是Jerry老師覺得最棒的一個收穫,是關於RAG應用,
當然活動中有不少介紹RAG的場次,但這場介紹的最好

何謂RAG

RAG範例

RAG的優勢

RAG搜尋

文字與圖片進行Chunking

多模態的混合

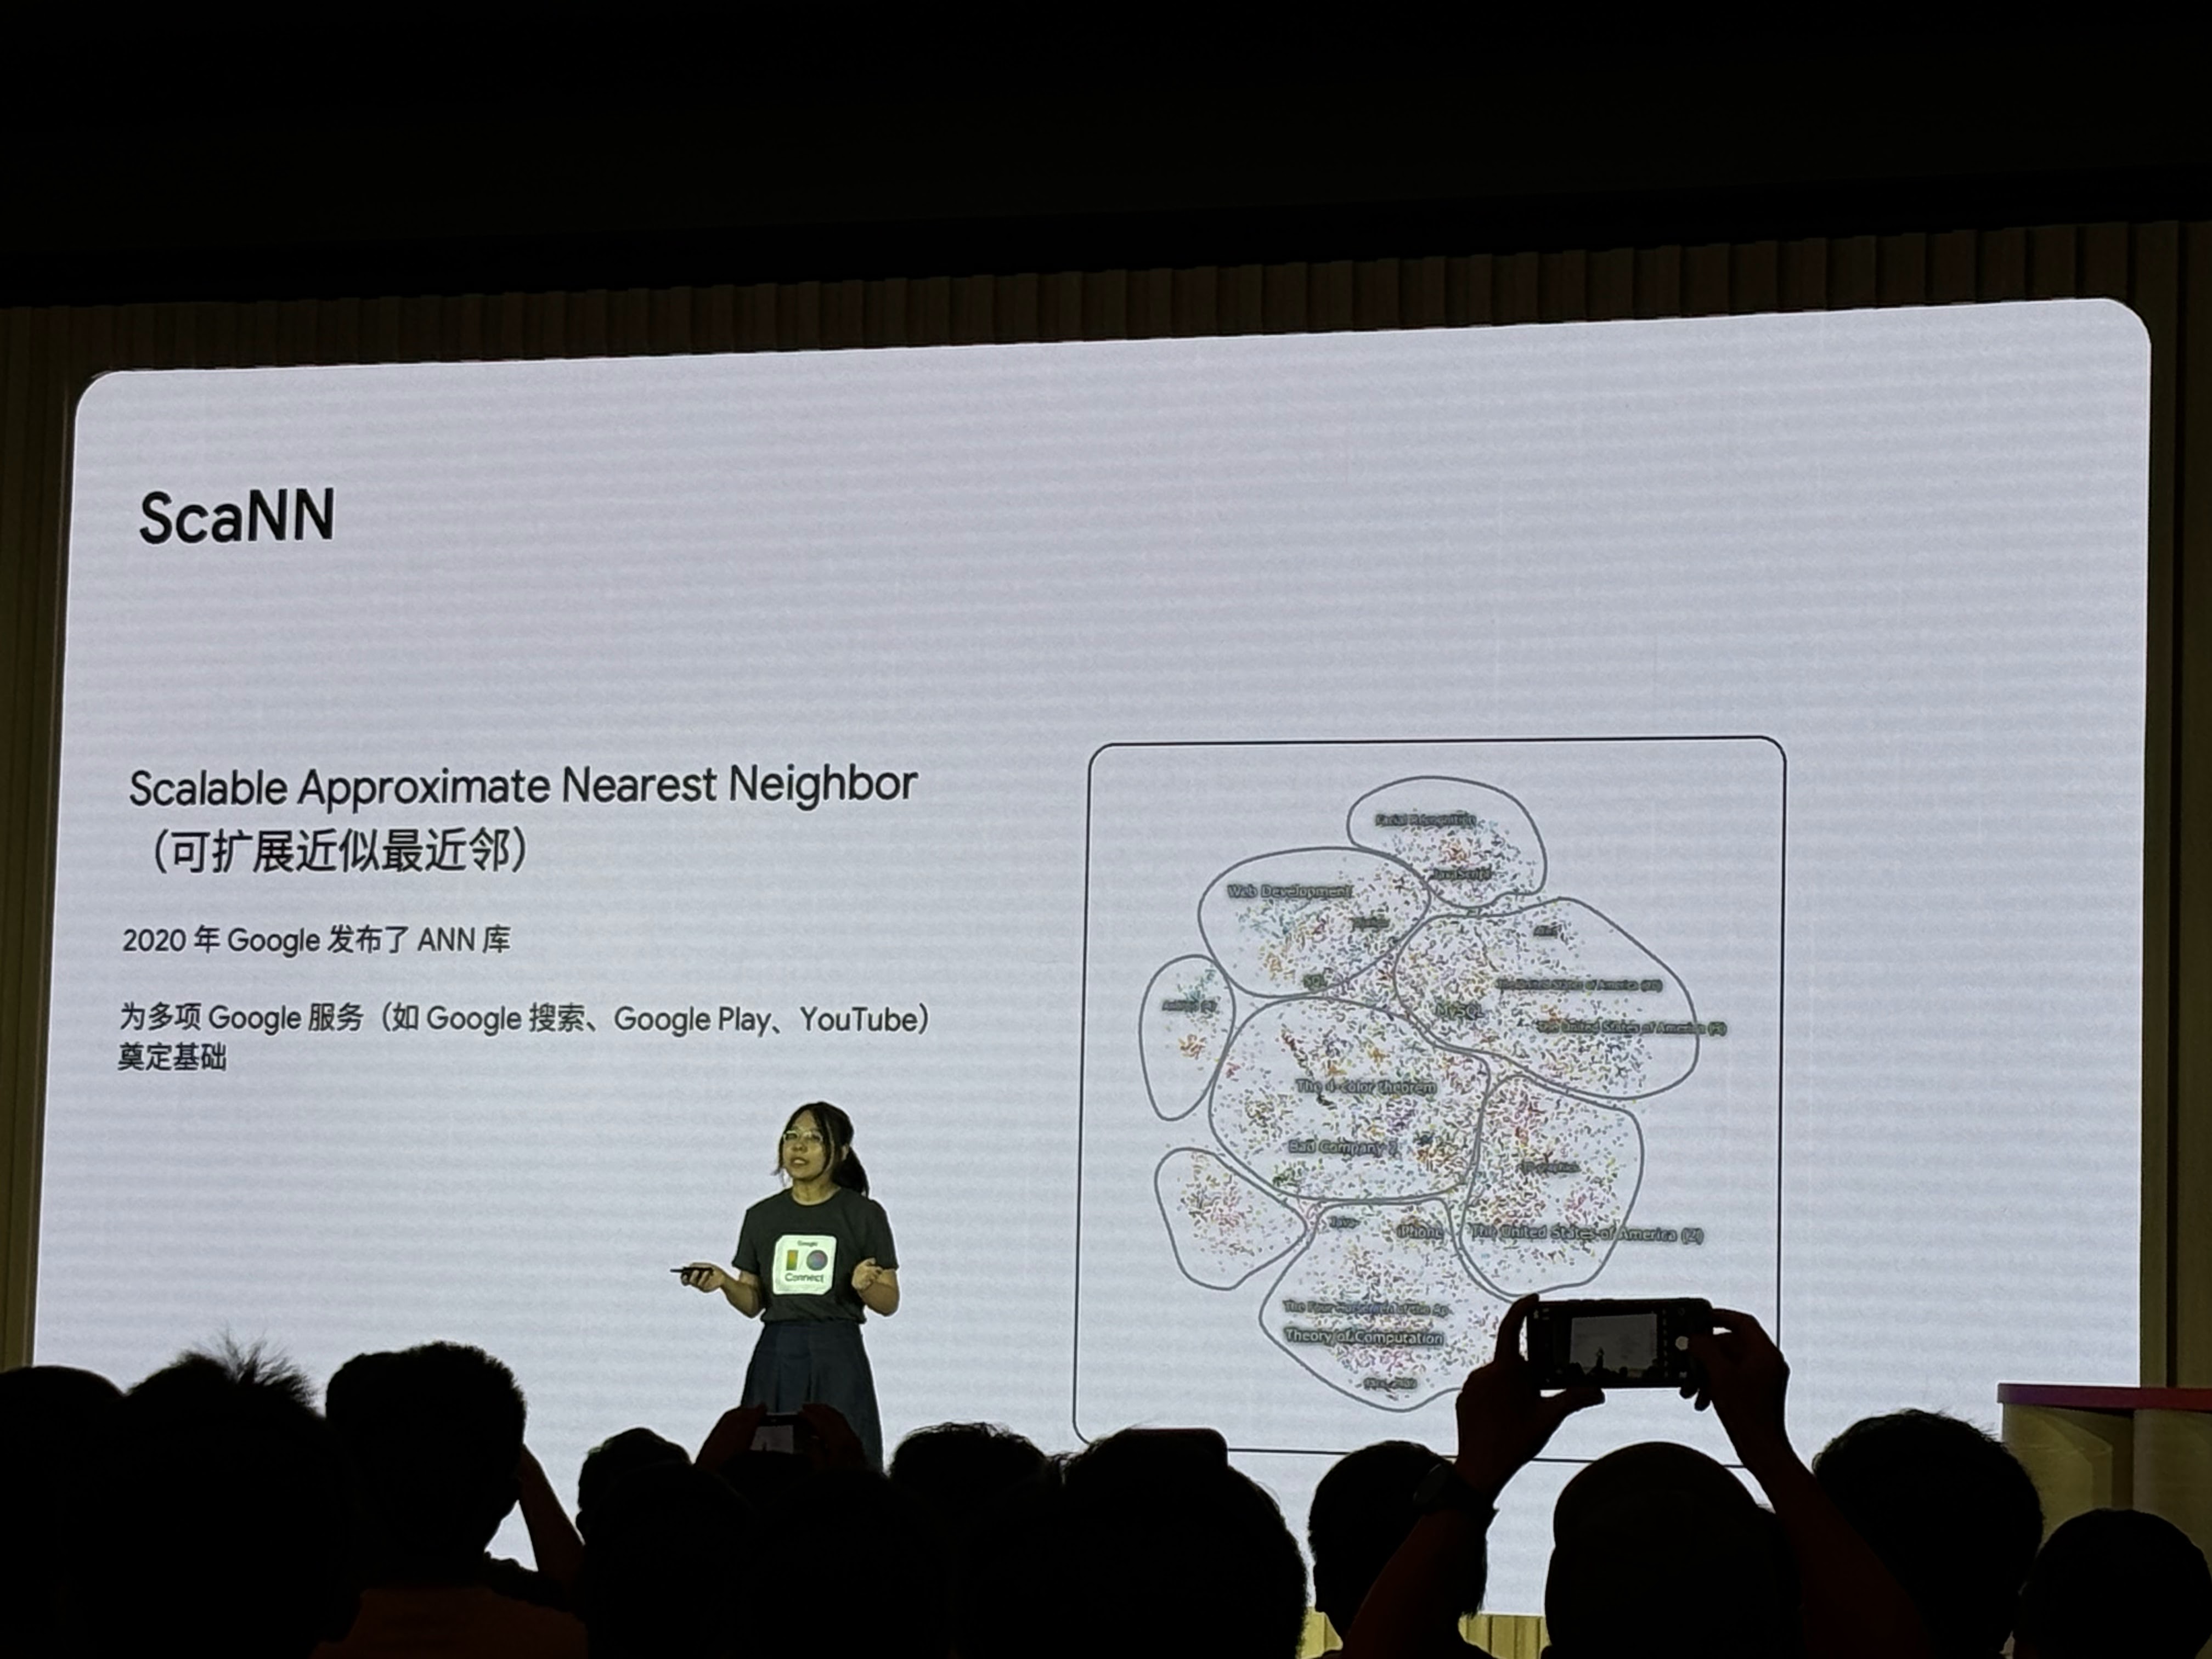
Google採用到目前為止最好的維度搜尋技術ScaNN

在Google Cloud上的引擎

混合搜尋,這塊也是近年大家的新作法

客製化RAG應用

智能分塊的概念也值得參考

的確是能強化RAG的做法之一

這個做法在開源也有類似的參考

捕捉真實答案的方法

接地氣的範例

這是 Uber的案例,比較像是搜尋+對話生成的方式

Uber的架構範例

Uber的架構範例


用多模態來讀論文(這種也是跟過去只讀文字是不同的)

範例流程

範例都在這裡


總結一下這次的心得,Google短短不到一年,

將所有產品圍繞Gemini + RAG,很期待接下來在整個生態的應用展開。

歡迎寫信給 jerry@ap-mic.com交流